WNM-3D: A World Navigation Model with 3D Scene Conditioning for Closed-Loop VLN
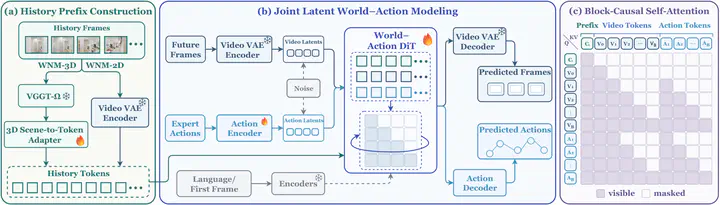 Image credit: WNM-3D authors
Abstract
WNM-3D is a generative world navigation model that jointly predicts future observations and navigation actions using persistent 3D scene context. A frozen geometry encoder processes monocular RGB history, and a trainable Scene-to-Token Adapter converts its features into a fixed-length prefix for a world-action Diffusion Transformer. Block-causal attention makes this geometric context available throughout future video-action generation. Training combines supervised learning from A*-generated demonstrations, DAgger-style adaptation on policy-visited states, and Counterfactual DanceGRPO refinement. Experiments on GN-Bench show stronger closed-loop navigation than VLM-based policies and a 2D-conditioned counterpart, with adaptation improving success and reinforcement learning further improving navigation success and path efficiency.