 Image credit: V-JEPA Policy authors
Abstract
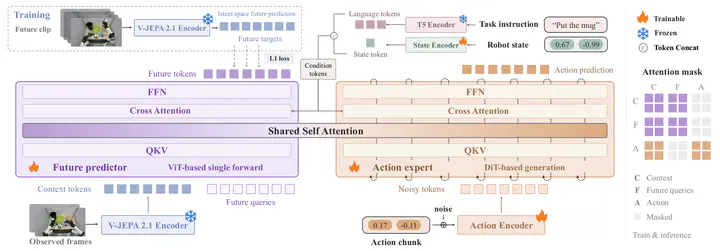
V-JEPA Policy investigates whether predictive visual representations can support effective world-action models without adapting a complete pretrained visual generator. A frozen V-JEPA 2.1 encoder supplies the visual latent space, while an instruction-conditioned future predictor and a flow-matching action expert are jointly trained from scratch. Future-informed predictor states condition action generation. With 0.9 billion total parameters and 0.6 billion trainable parameters, the model performs competitively on LIBERO, LIBERO-Plus, and RoboCasa-GR1. Comparisons under matched training budgets show advantages over other visual representations, particularly under distribution shifts. Predictor pretraining on DROID video-instruction pairs without action labels further improves downstream control and generalization.