KODA: Kinematics–Observation Data Alignment for Humanoid Learning from Human Egocentric Demonstration
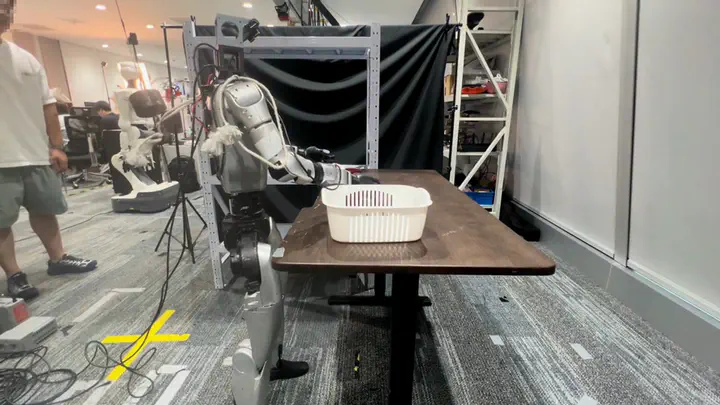 Image credit: KODA authors. Thumbnail cropped from robot experiments.
Abstract
KODA converts egocentric human demonstrations into aligned training data for humanoid whole-body vision-language-action policies. It first produces a simulation-checked motion trajectory, then uses the corresponding camera poses to synthesize robot-view observations. Motion, observations, and instructions are stored as a reusable canonical record. Controller-specific states and action labels are regenerated by optimizing commands to follow that motion. Evaluations on four Unitree G1 loco-manipulation tasks with SONIC and HEFT show improved generalization to conditions covered by human demonstrations but absent from robot demonstrations, with gains increasing across the evaluated human-data budgets.
Type
Publication
arXiv preprint, 2026